Background - average cell discrepancy
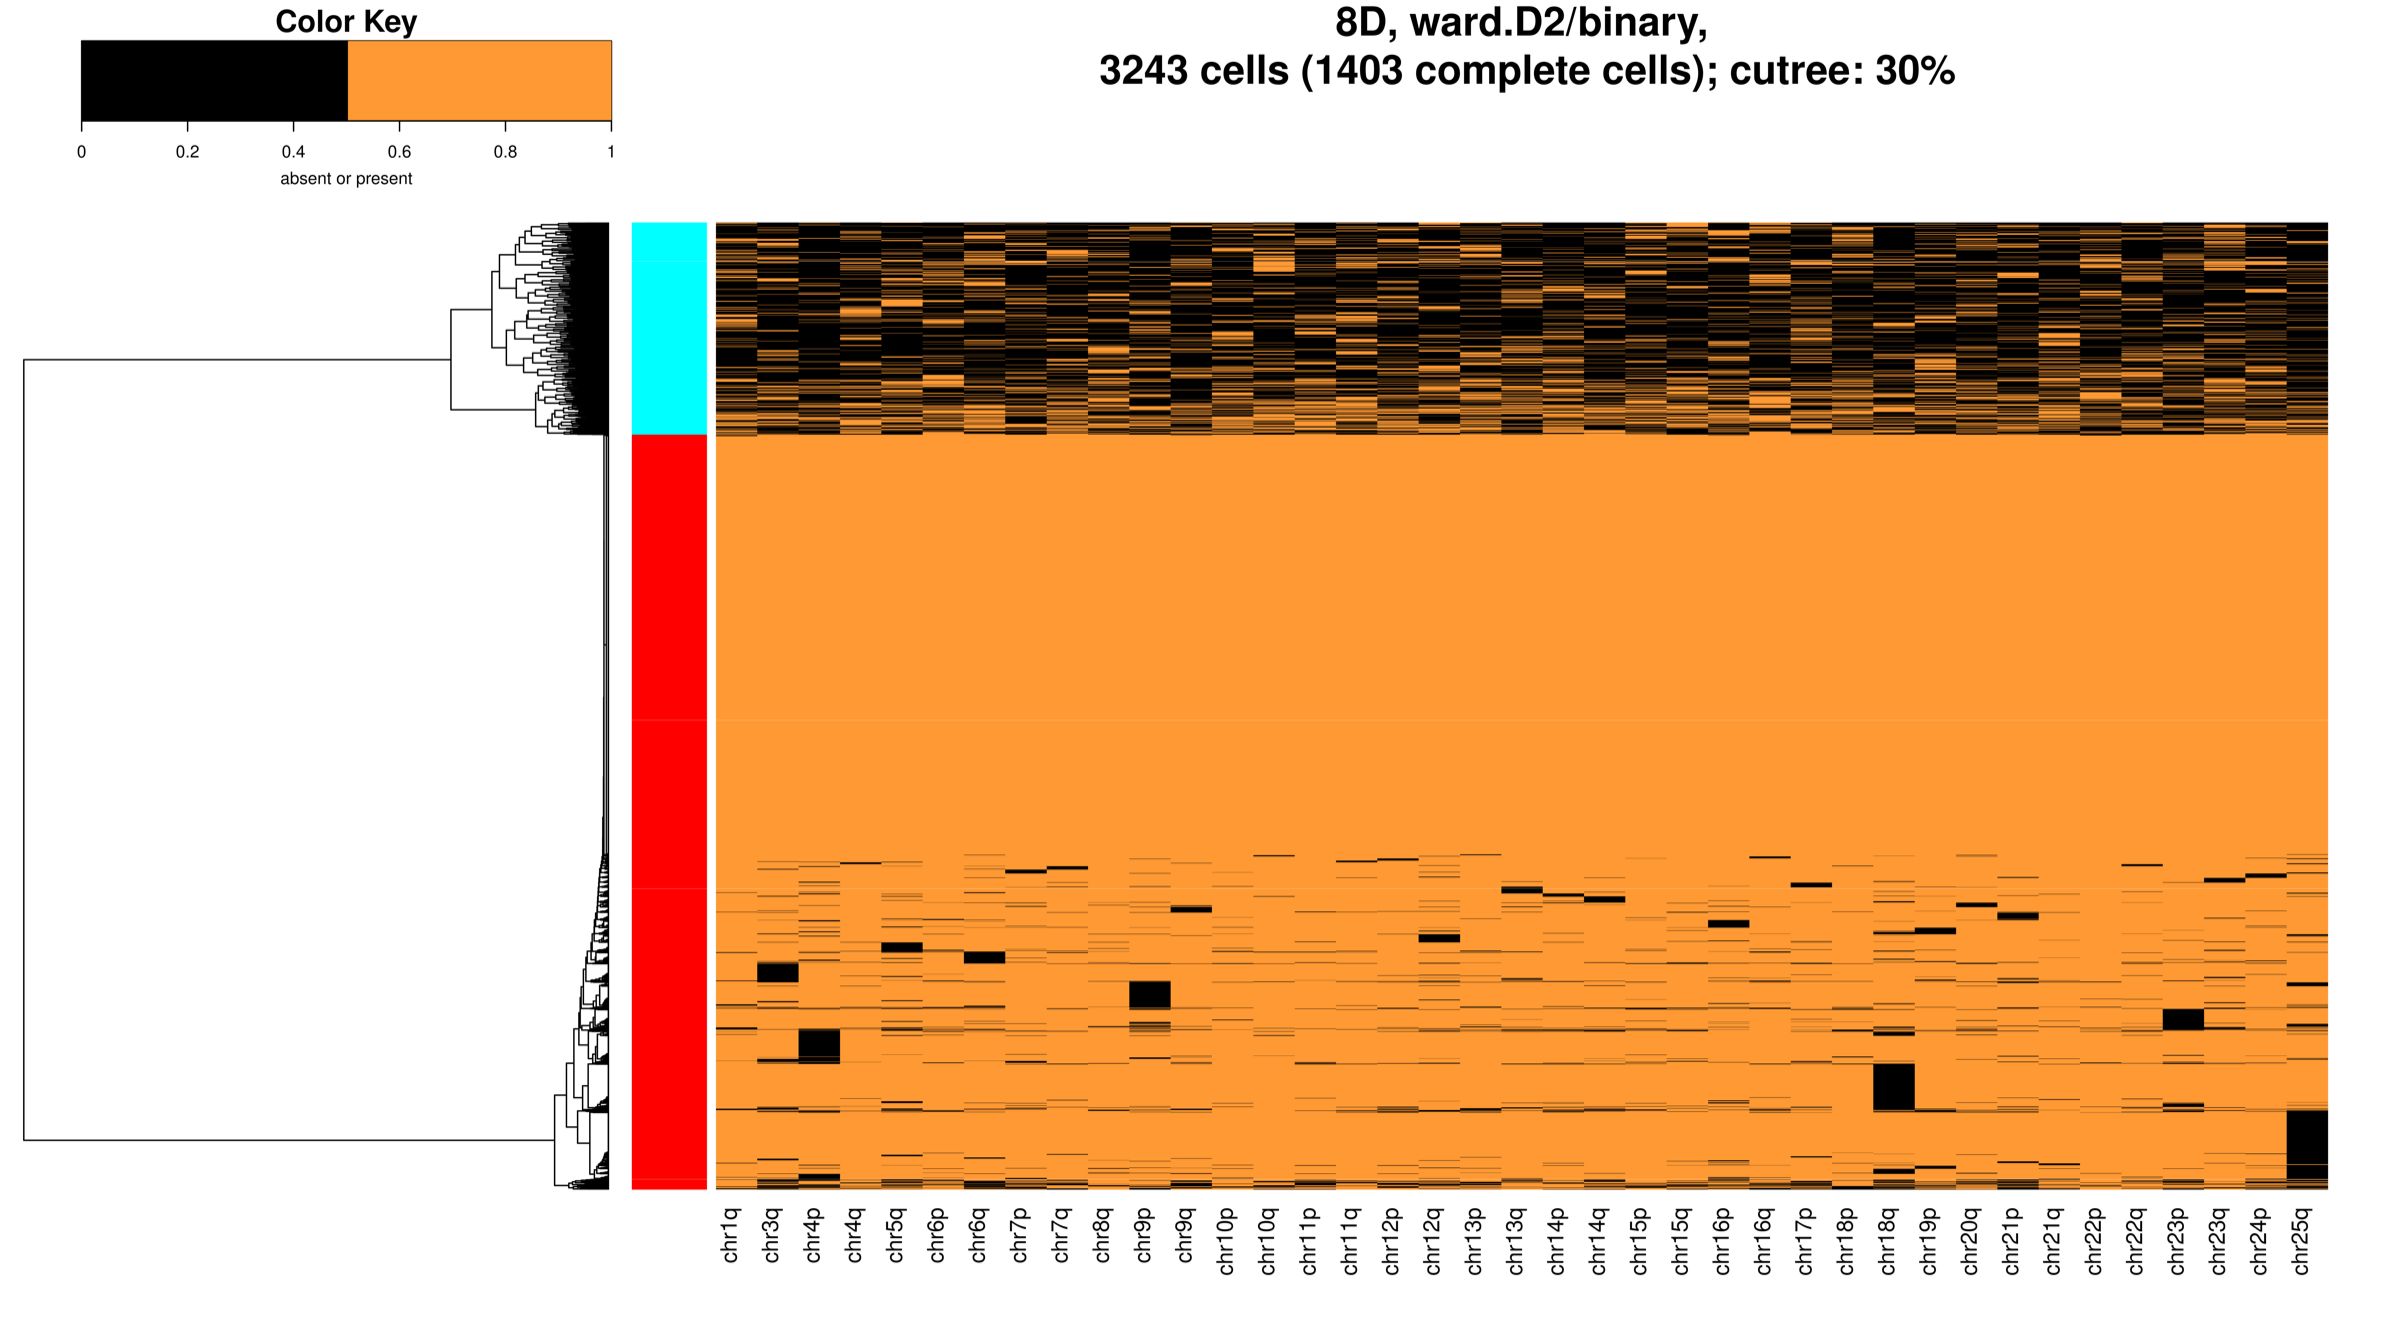
Download original image: Cell-by-chromosome-arm calls before cluster selection
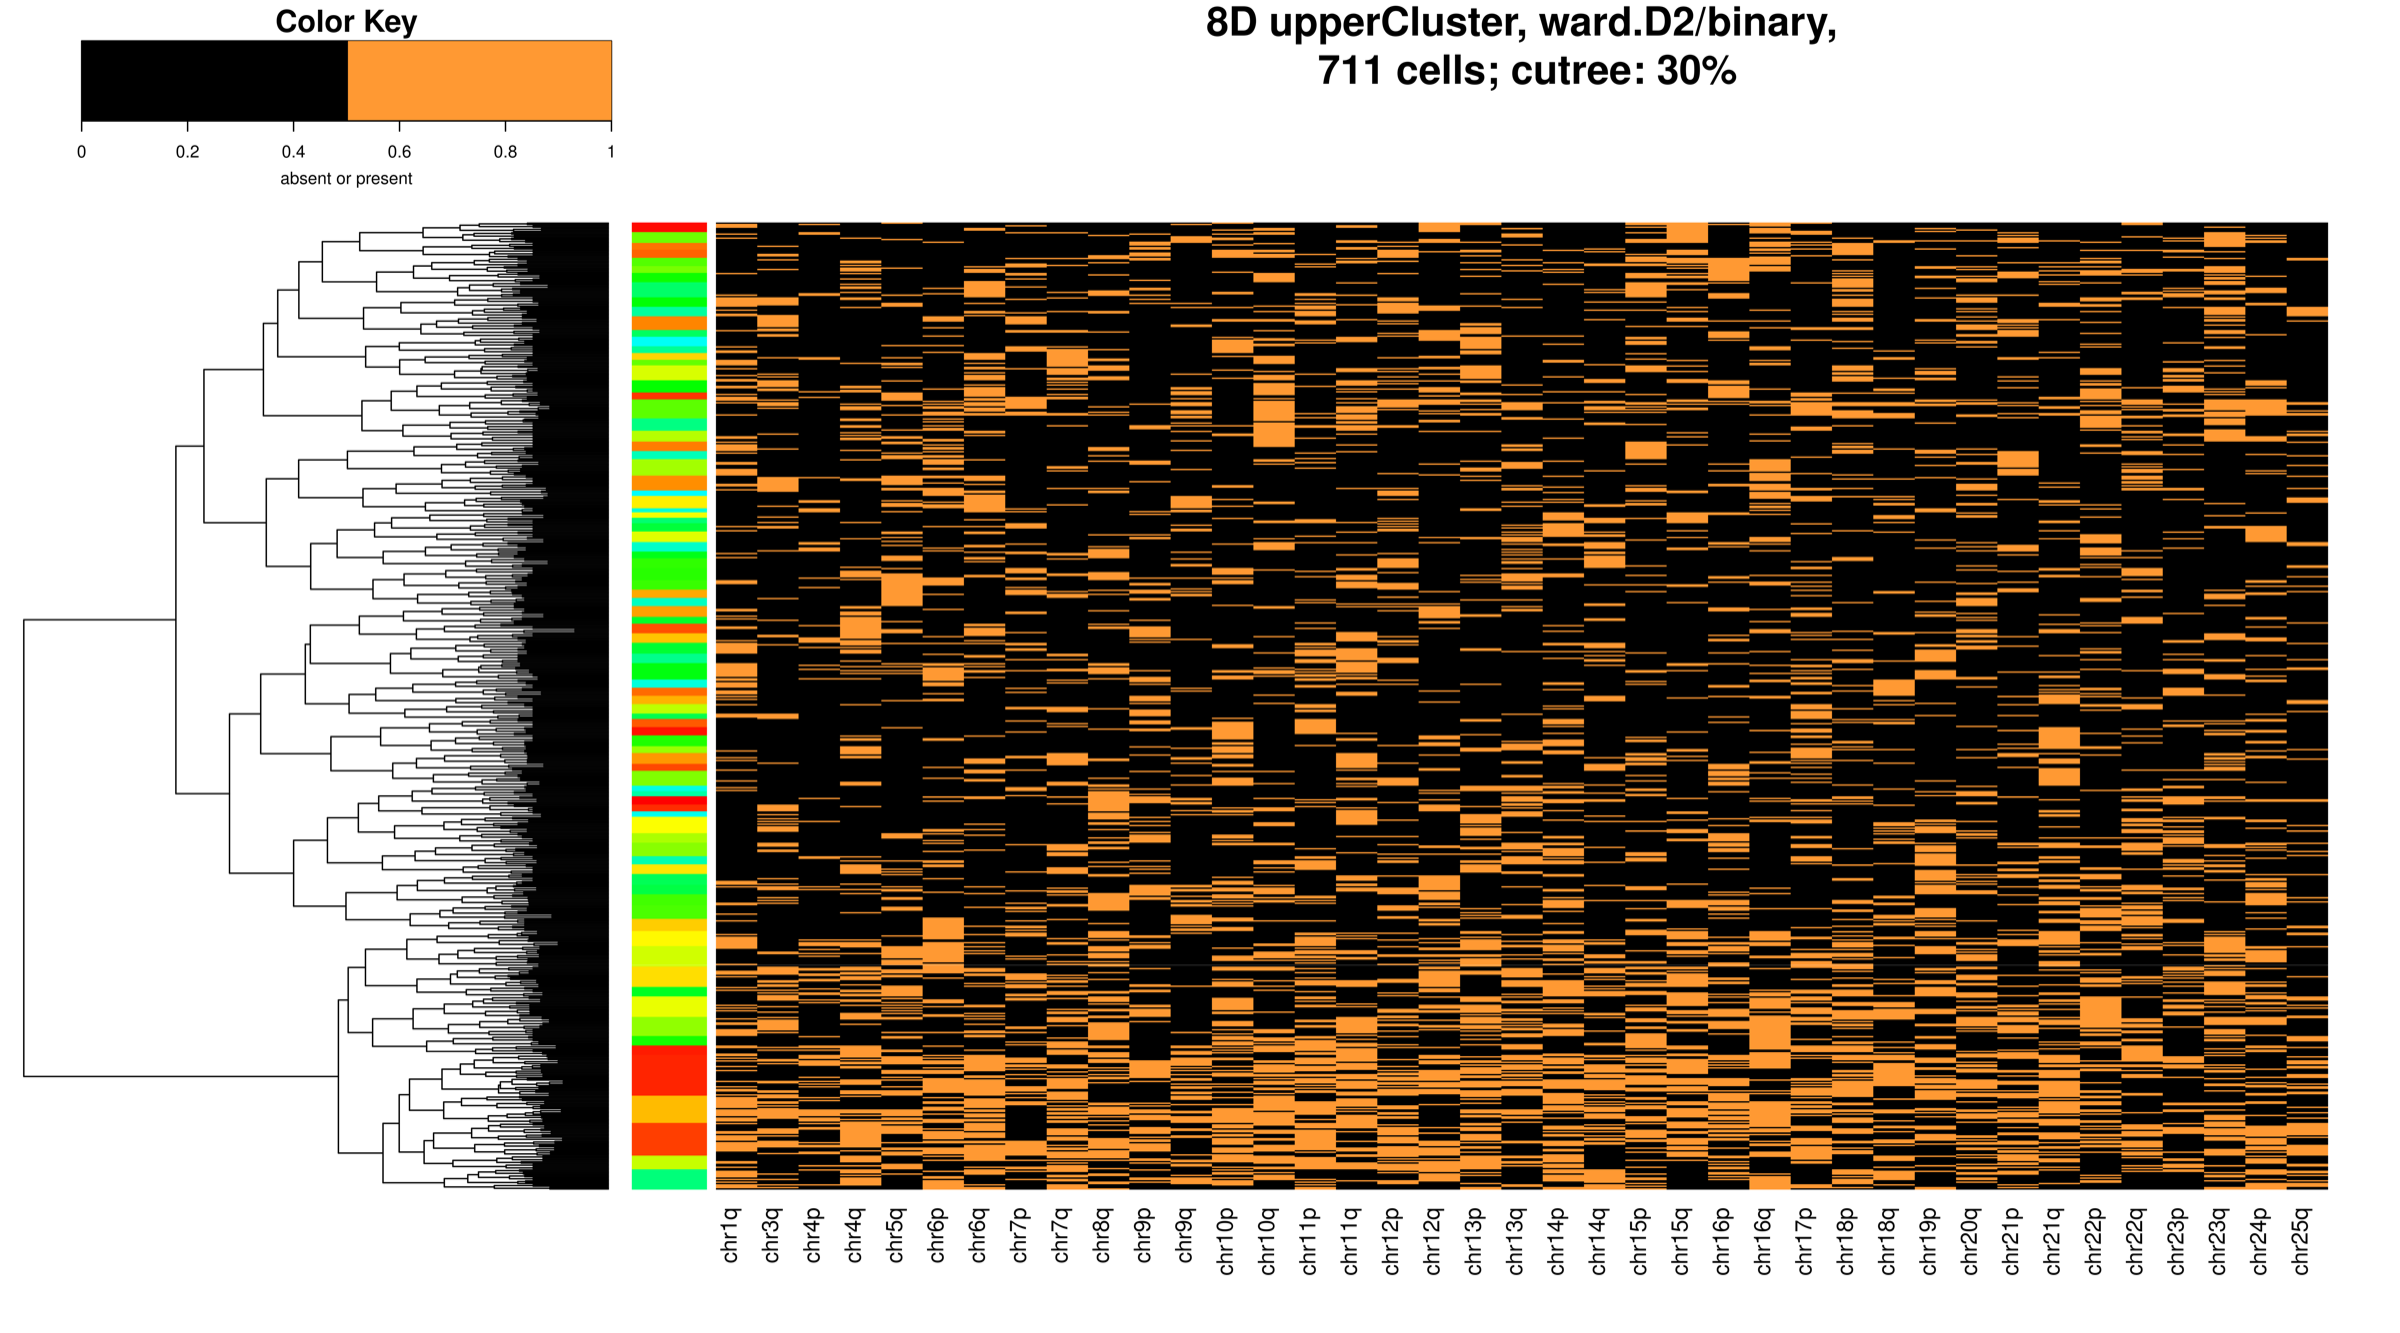
Download original image: Cell-by-chromosome-arm calls in the selected cluster
Cell discrepancy
| arm1 | arm2 | arm3 | arm4 | |
| cell 1 | 1 | 0 | 1 | 0 |
| cell 2 | 1 | 1 | 1 | 0 |
These two cells disagree at one of four arms: cell discrepancy = 1/4 = 25%. For a collection of cells, evaluate every distinct cell pair and take the average discrepancy.
Purpose
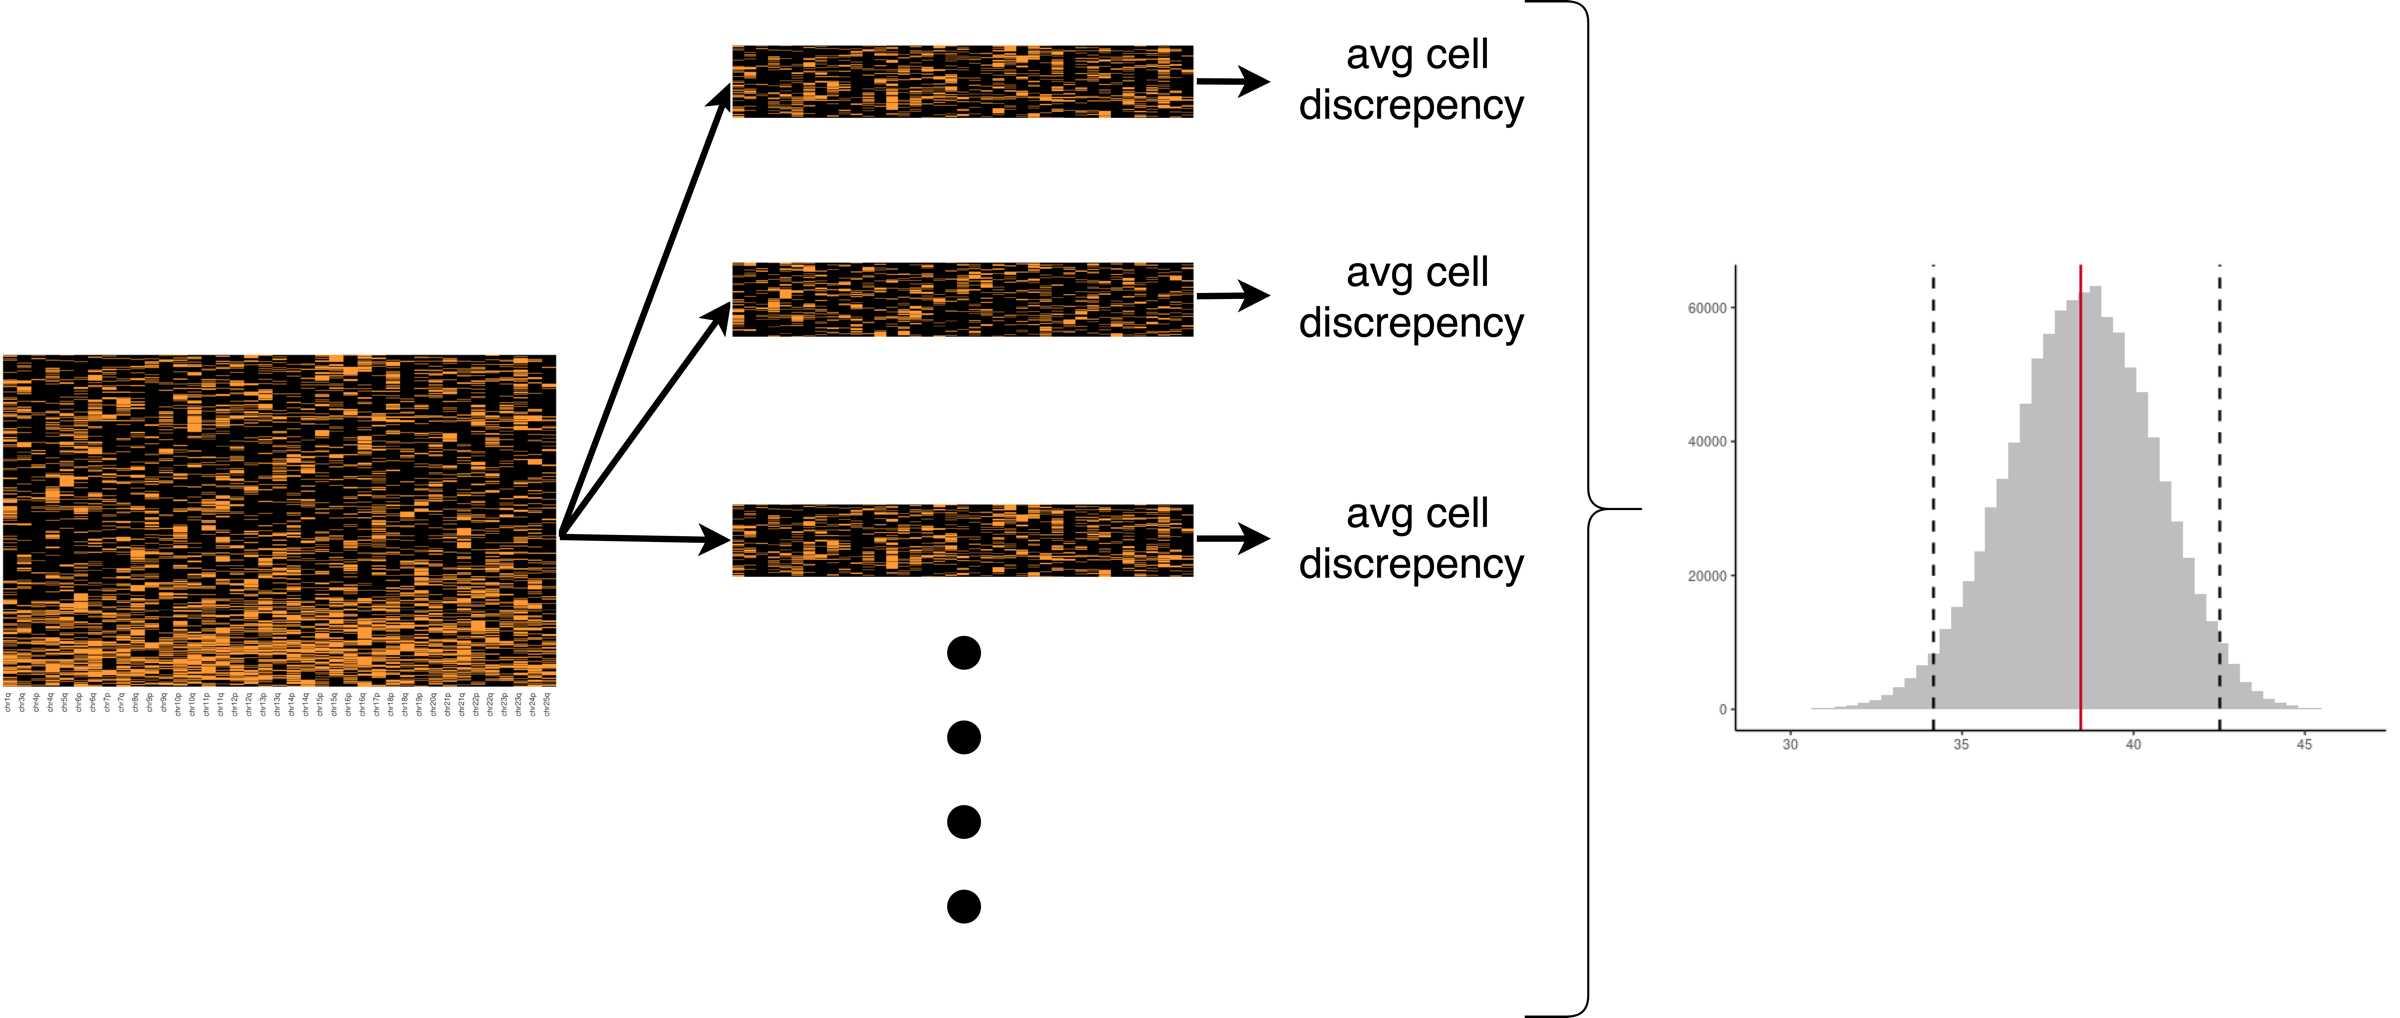
Download original image: Average cell discrepancy and the resampling question
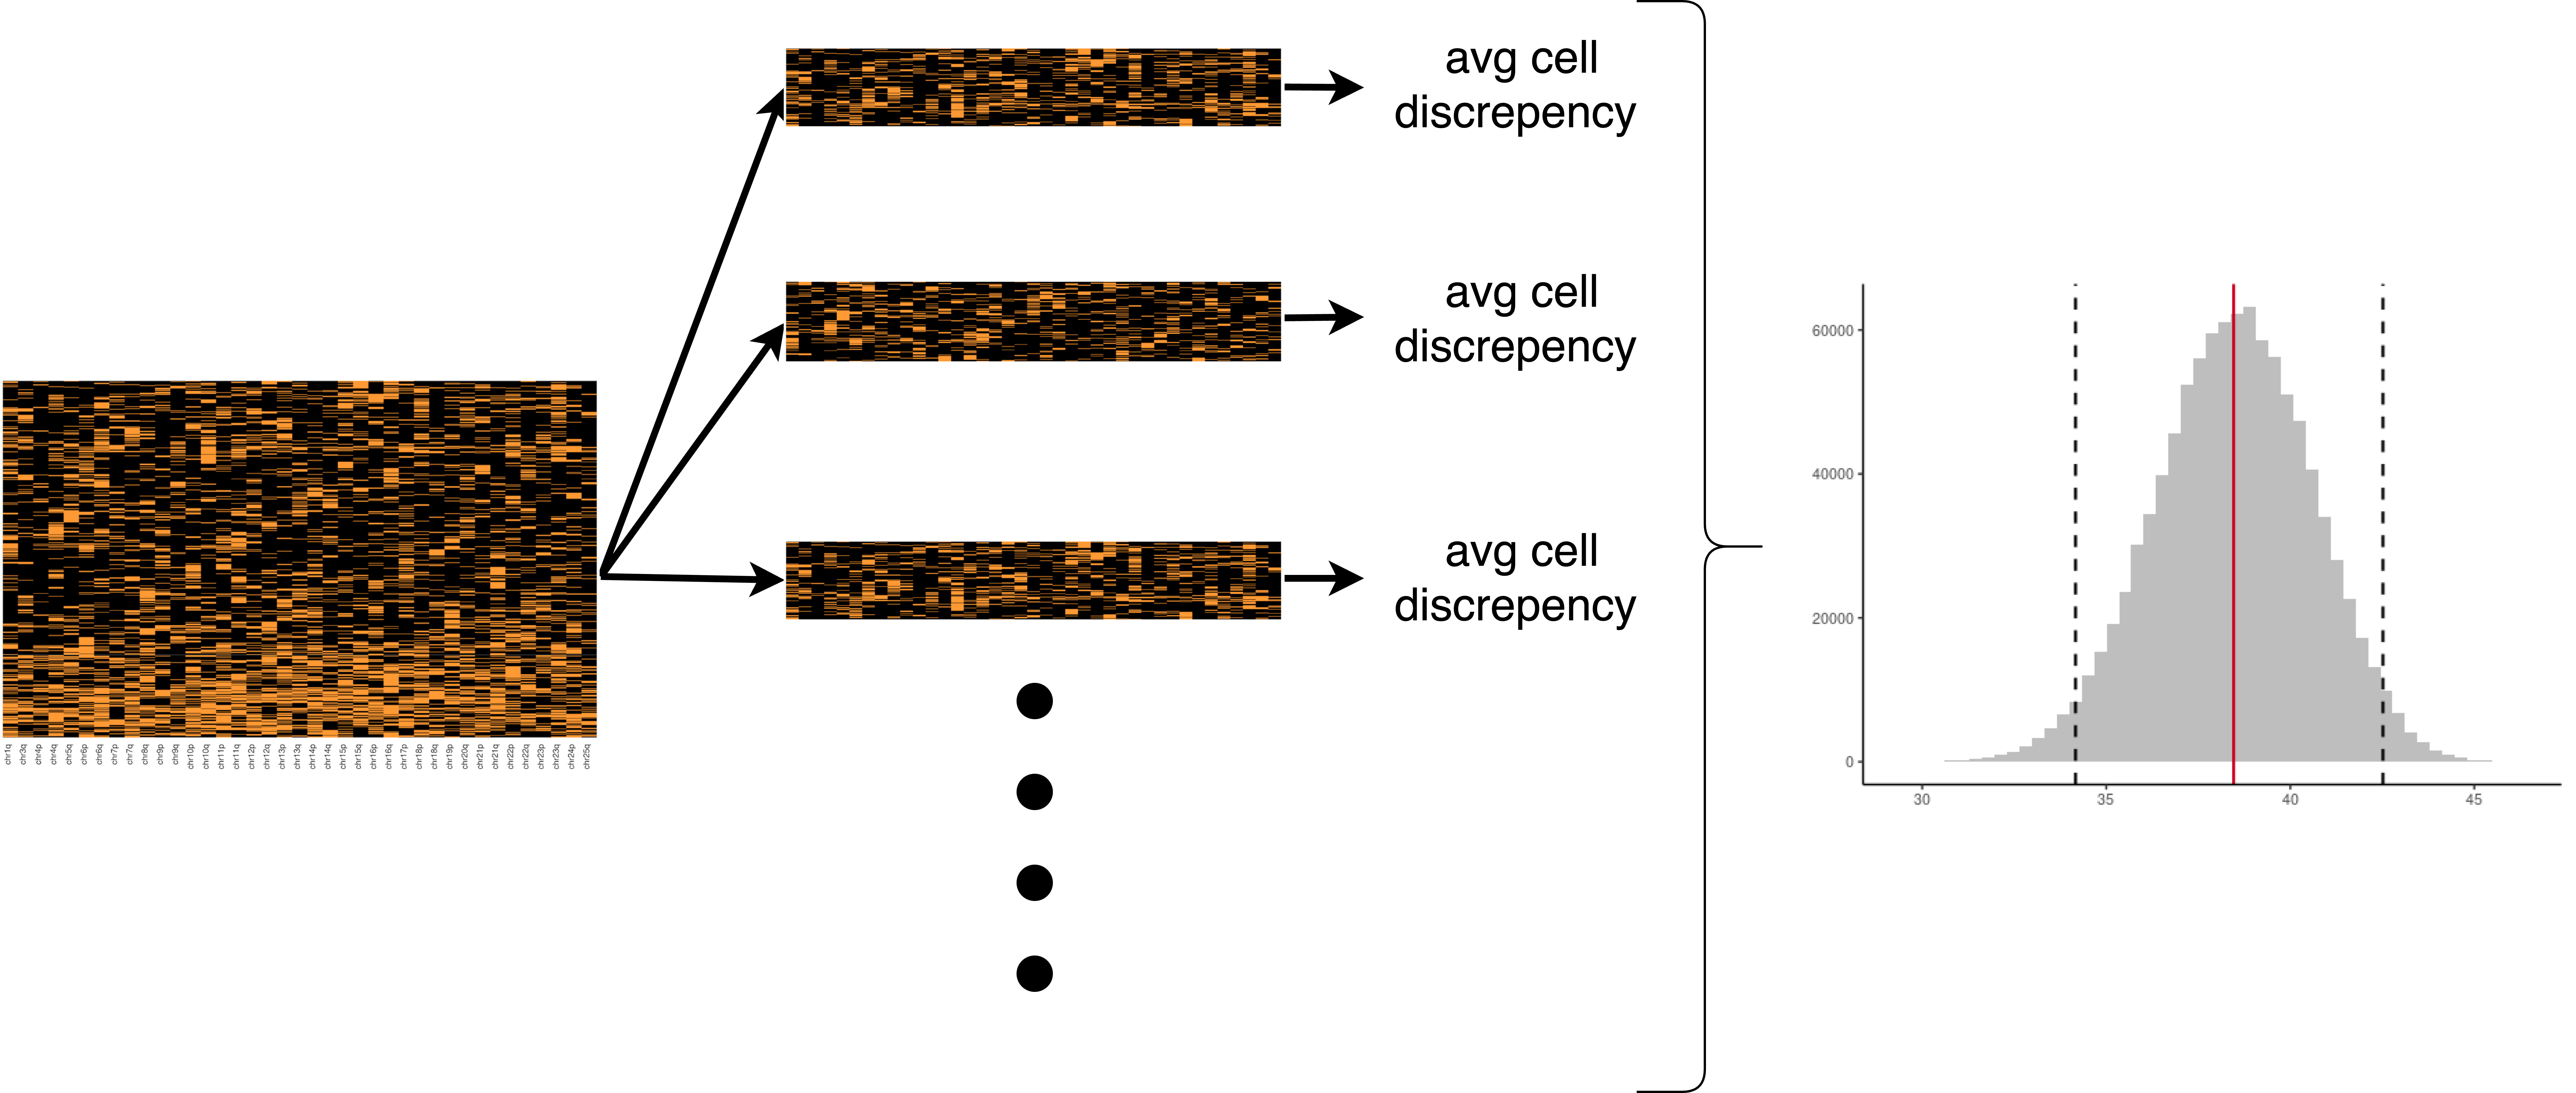
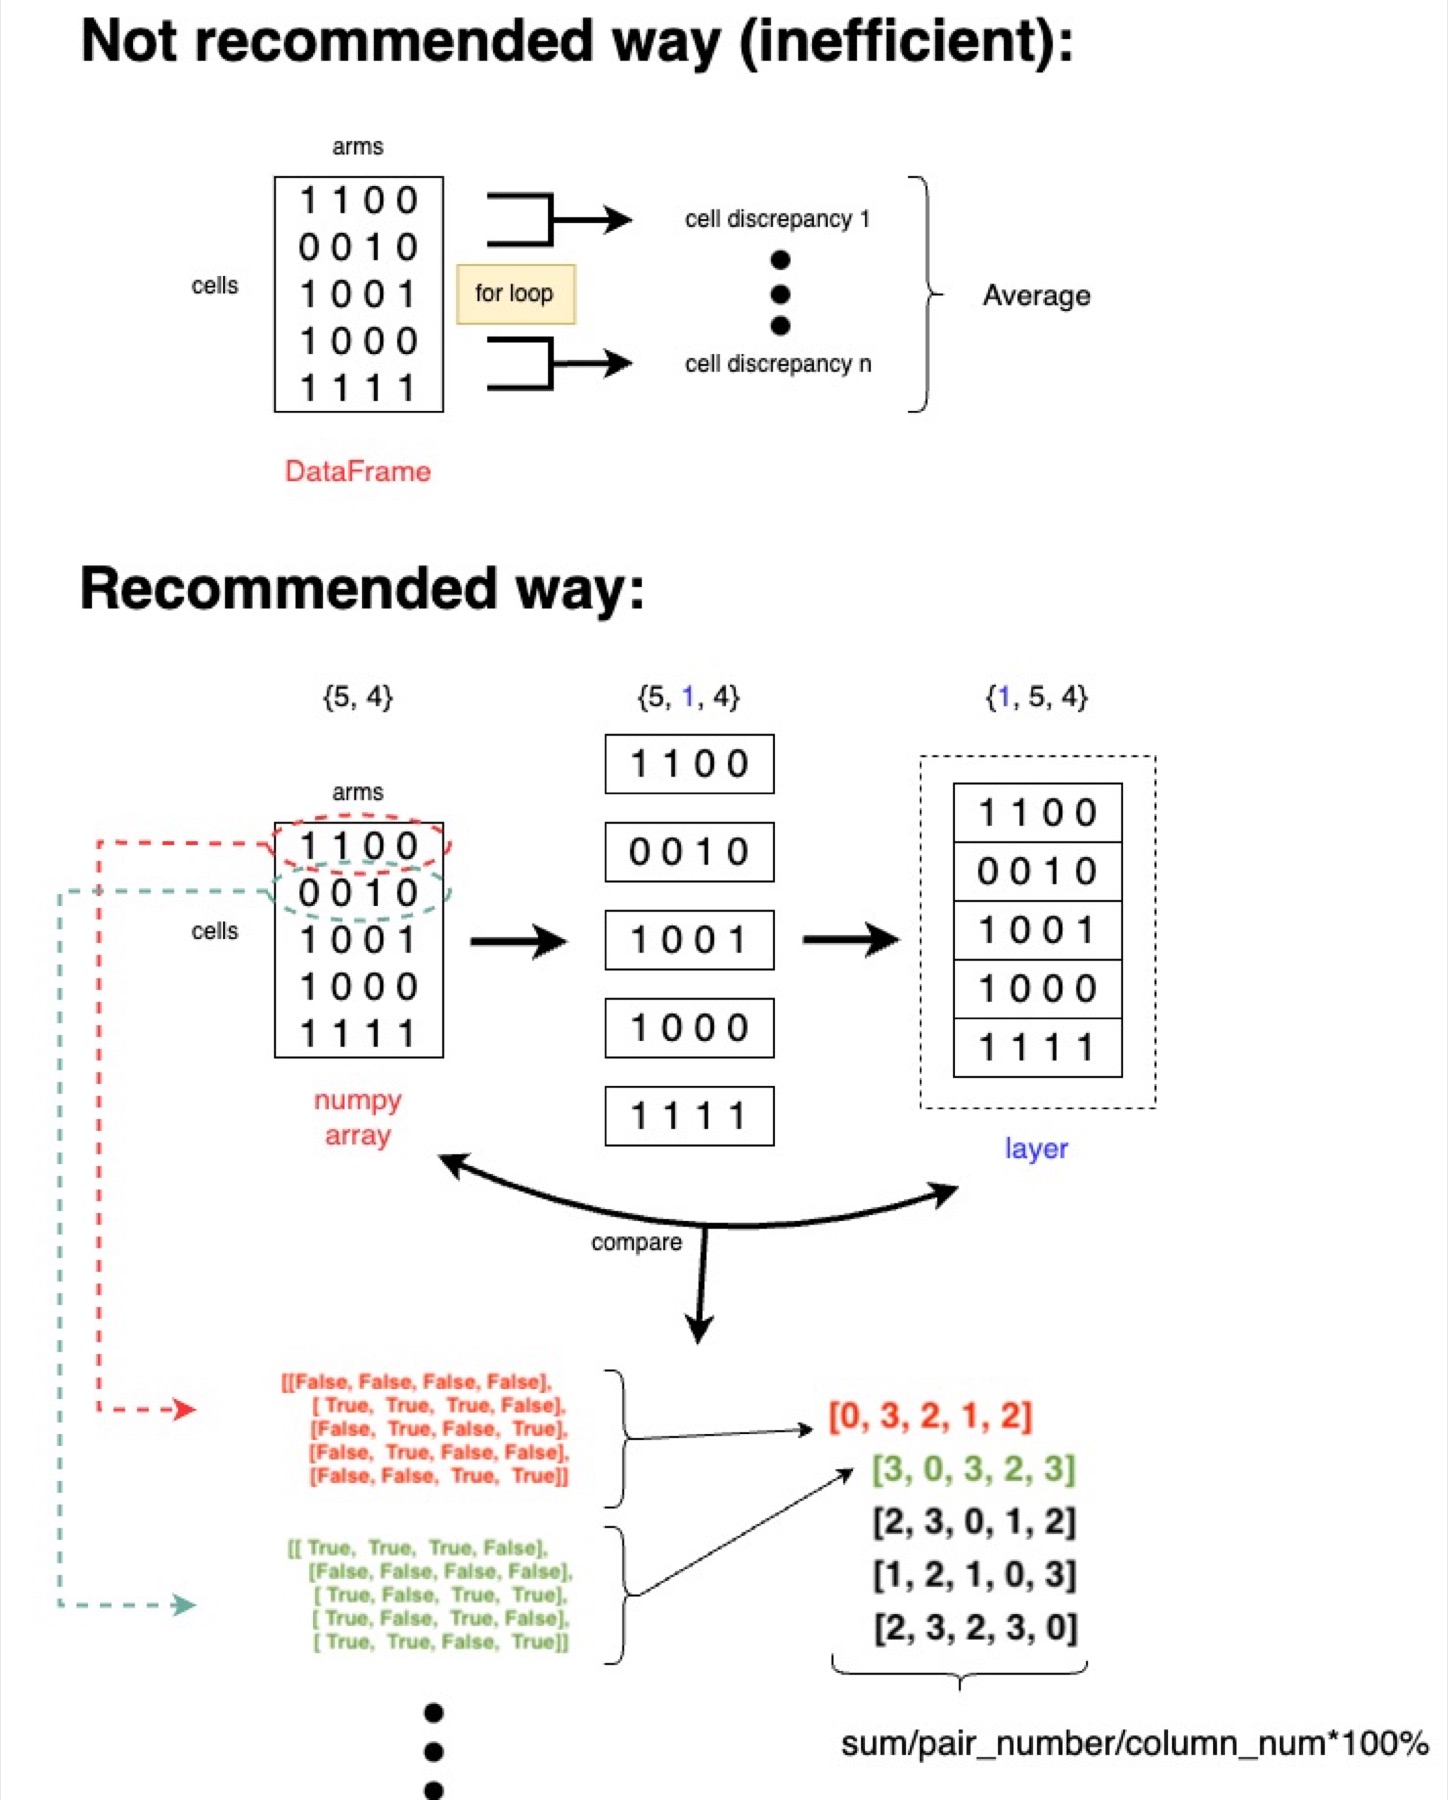
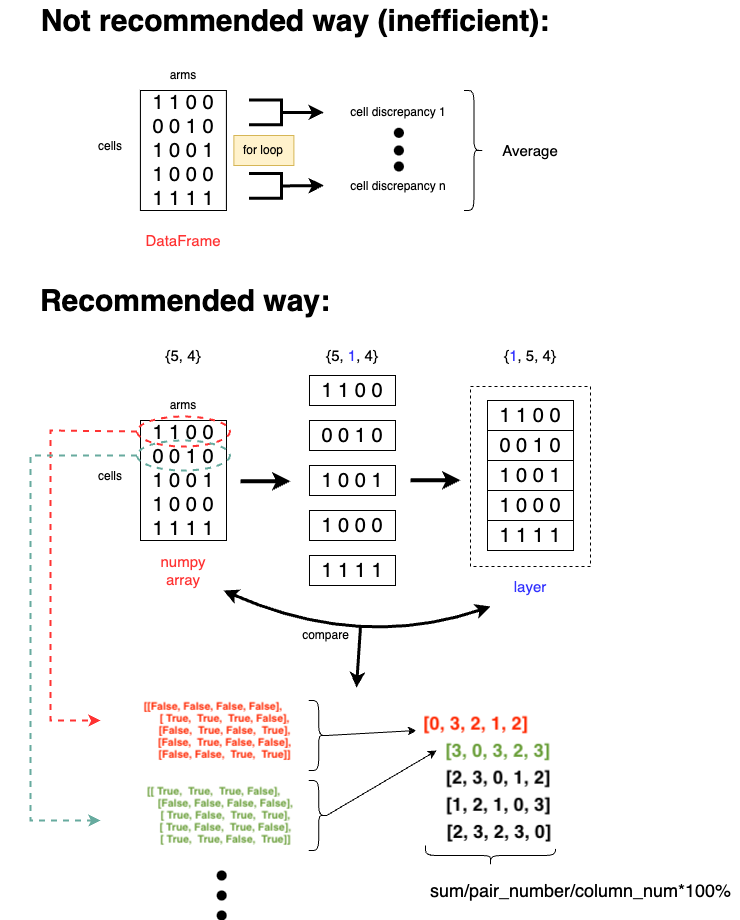
Reducing computation time
- Vectorize the pairwise calculation
- Parallel Computing
bootstrap_discrepancy.py
#!/usr/bin/env python3
# -*- coding: utf-8 -*-
"""
Created on Mon Mar 11 16:28:51 2024

@author: Jordan
"""

import sys
from concurrent.futures import ProcessPoolExecutor
import pandas as pd
import numpy as np
import csv
import math

def subset_matrix_sampling(matrix, cell_n):
    """Samples a subset of the matrix."""
    assert len(matrix) >= cell_n, "The cell number you want to subset is >= total cells in the data."
    return matrix.sample(n=cell_n, replace=False)

def calculate_mismatches(subset_matrix):
    """Vectorized calculation of mismatches across a subset matrix."""
    n = subset_matrix.shape[0] # nrow
    expanded_matrix = np.expand_dims(subset_matrix.to_numpy(), axis=1)  # Expand dims to enable broadcasting, see explanation in this notion
    mismatches = np.sum(expanded_matrix != expanded_matrix.transpose((1, 0, 2)), axis=2)
    np.fill_diagonal(mismatches, 0)  # change self-self comparison to 0 mismatch (just for safety)
    return np.sum(mismatches) / (n * (n - 1)) * 100 / subset_matrix.shape[1]

def process_iteration(args):
    """Function for parallel execution: samples subset and calculates mismatches."""
    matrix, cell_n = args
    subset_matrix = subset_matrix_sampling(matrix, cell_n)
    return calculate_mismatches(subset_matrix)

def main(csv_file_path, cell_n, bootstrap_n, output_file_path, threads):
    print("Loading data...")
    raw_matrix = pd.read_csv(csv_file_path, index_col=0)

    bootstrap_max_n = math.comb(len(raw_matrix), cell_n)
    assert bootstrap_n <= bootstrap_max_n, "Bootstrap_n is too high, decrease it or increase cell_n."

    args_list = [(raw_matrix, cell_n) for _ in range(bootstrap_n)]

    print("Processing...")
    with ProcessPoolExecutor(max_workers=threads) as executor:
        results = list(executor.map(process_iteration, args_list))

    print("Saving results...")
    with open(output_file_path, 'w', newline='') as file:
        writer = csv.writer(file)
        for number in results:
            writer.writerow([round(number, 2)])

    print(f"CSV file '{output_file_path}' has been created successfully.")

if __name__ == "__main__":
    if len(sys.argv) != 6:
        print("Usage: python3 bootstrap_discrepancy.py <path_to_csv_file> <cell_number_to_subset> <bootstrap_n> <output_file_path> <threads_num>")
        sys.exit(1)

    main(sys.argv[1], int(sys.argv[2]), int(sys.argv[3]), sys.argv[4], int(sys.argv[5]))
Usage:
python3 bootstrap_discrepancy.py <path_to_csv_file> <cell_number_to_subset> <bootstrap_n> <output_file_path> <threads_num>cell_number_to_subset: number of cells sampled in each iteration.bootstrap_n: number of bootstrap iterations.threads_num: number of worker threads.