Goal:
**Identify DEGs in “interaction term” using pairwise comparisons. **
What is “interaction term”?
In typical pairwise comparison, we found the DEGs between group ctrl and treatment (maybe at certain timepoints).
However, if we have **strain and treatment **(two variables)(eg., 2*strains (WT, ero1) vs 2*treatments (25C, tm)), we can test the “interaction term”:
In addition to discovering DEGs between control and treatment groups, we can also discover the DEGs in the interaction term strainero1.treatmenttm → DEGs are those genes that respond to the tm treatment differently due to different strains.
However, we SPLIT the samples to *different sample sets *before performing DESeq2.
The idea is that because an interaction term can appear in different sample sets
- 2*strains (WT, ero1) + 2*treatments (25C, tm)
- 3*strains (WT, ero1, eK) + 3*treatments (25C, tm, 35C)
Both sample sets have the interaction term
strainero1.treatmenttm→ we perform the intersection of DEGs discovered in the same interaction terms from these sample sets
Workflow:
- Split samples to 4 sample sets and discover DEGs in interaction terms
- Using all sample (not split) to discover DEGs in interaction terms
- Intersection
Example:
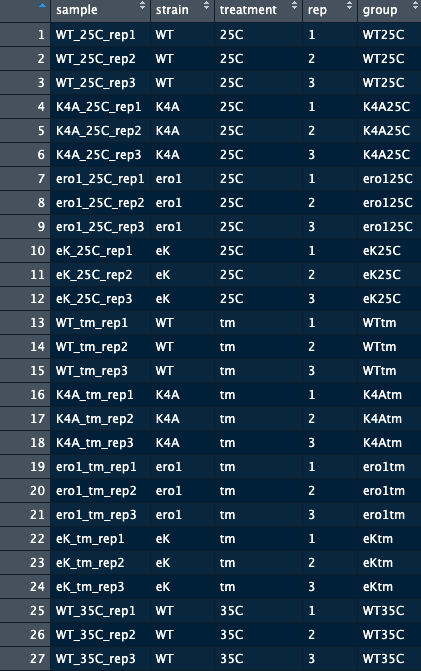
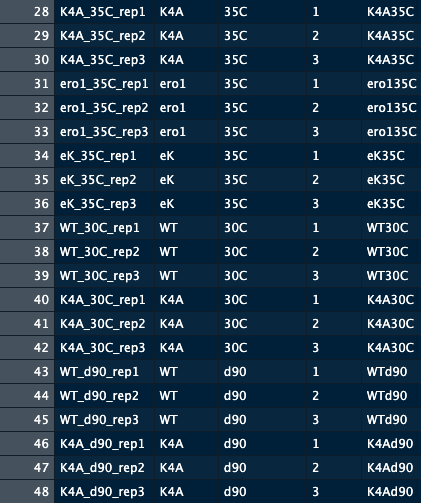
Samples (experimental design):
4 strains: WT, K4A, ero1, eK
5 treatments: 25C, tm, 35C, 30C, d90
3 replications: rep1 ~3
Library and Data Import
library(DESeq2)
library(ashr)
library(sva)    # for batch correction
library(corrplot)    # for correlation plot
library(ggvenn)    # for Venn Diagram
library(car)  # point labels without overlaps
library(umap) # umap
library(tibble)
library(readr)
library(ggplot2)
library(ggrepel)
library(EnhancedVolcano)
counts_raw <- read_delim("//counts_matirx.txt",
delim = "\t", escape_double = FALSE,
trim_ws = TRUE)
counts_raw <- counts_raw %>% column_to_rownames(var="Geneid")
metadata <- read_delim("metadata.txt", delim = "\t",
escape_double = FALSE, trim_ws = TRUE)
geneID_transform <- read_delim("~//04_featureCounts/ID_table.txt",
delim = "\t", escape_double = FALSE,
trim_ws = TRUE)
names(geneID_transform)[1] <- c("Gene")
metadata$strain <- factor(metadata$strain, levels = c("WT", "K4A", "ero1", "eK"))
metadata$treatment <- factor(metadata$treatment, levels = c( "25C", "tm", "35C", "30C", "d90"))
metadata$rep <- factor(metadata$rep, levels = c(1,2,3))
metadata$group <- factor(paste0(metadata$strain,metadata$treatment))Split samples to 4 sample sets and discover DEGs in interaction terms
Identify DEGs for the strainero1.treatmenttm interaction term.
Sample set 1: WT_25C / ero1_25C / WT_tm / ero1_tm
Subset
counts_raw_1 <- subset(counts_raw,
                       select = grepl("WT_25C|WT_tm|ero1_25C|ero1_tm",
                                     names(counts_raw)))

metadata_1 <- metadata[metadata$group %in% c("WT25C","WTtm","ero125C","ero1tm"),]
Pre-filter and DESeq2
# the read count cut-off of the low-expression genes
low_exp_read_count = 5
# minimum samples that express this gene (總共有 48 個 sample)
minimum_exp_sample = ncol(counts_raw_1)/2


dds_1 <- DESeqDataSetFromMatrix(countData= round(counts_raw_1),
                              colData= metadata_1,
                              design= ~ strain + treatment + strain:treatment + rep) # batch effect

keep <- rowSums(counts(dds_1) > low_exp_read_count) >= minimum_exp_sample
dds_1 <- dds_1[keep, ]

# 5901 genes
plotDispEsts: inspect the fit; this example uses fitType = local throughout
dds_wald_local_1 <- DESeq(dds_1,
              test = "Wald",
              fitType = "local",
              betaPrior = F)

summary(results(dds_wald_local_1))
out of 5901 with nonzero total read count
adjusted p-value < 0.1
LFC > 0 (up) : 886, 15%
LFC < 0 (down) : 1121, 19%
outliers [1] : 11, 0.19%
low counts [2] : 0, 0%
(mean count < 4)Check resultsNames: the first factor level is the reference
dds_wald_local_1$strain
dds_wald_local_1$treatment
resultsNames(dds_wald_local_1)[1] WT WT WT ero1 ero1 ero1 WT WT WT ero1 ero1 ero1
Levels: WT ero1
[1] 25C 25C 25C 25C 25C 25C tm tm tm tm tm tm
Levels: 25C tm
[1] "Intercept" "strain_ero1_vs_WT" "treatment_tm_vs_25C" "strainero1.treatmenttm"**DEGs of **strainero1.treatmenttm
The treatment-induced change differs between WT and ero1.
Extract results of the interaction term strainero1.treatmenttm
result1_strainero1.treatmenttm <-results(dds_wald_local_1,
                                 name="strainero1.treatmenttm",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result1_strainero1.treatmenttm_df <- as.data.frame(result1_strainero1.treatmenttm)
result1_strainero1.treatmenttm_df <- result1_strainero1.treatmenttm_df[order(result1_strainero1.treatmenttm_df$padj),]


# check if any genes has baseMean = 0?
result1_strainero1.treatmenttm_df[result1_strainero1.treatmenttm_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result1_strainero1.treatmenttm_df[is.na(result1_strainero1.treatmenttm_df$pvalue) & is.na(result1_strainero1.treatmenttm_df$padj),]
# -> 11 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result1_strainero1.treatmenttm_df[is.na(result1_strainero1.treatmenttm_df$padj) & !is.na(result1_strainero1.treatmenttm_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result1_strainero1.treatmenttm)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 4.248606
# as a result, 0% of genes were filtered out of the analysis


result1_strainero1.treatmenttm_df <- na.omit(result1_strainero1.treatmenttm_df) # 5890 gene

write.csv(result1_strainero1.treatmenttm_df, file = "DEG_Interaction/01_WT&ero1.vs.tm&25C/DESeq2_res_strainero1.treatmenttm_no.lfcShrink.csv")
lfcShrink (ashr)
# "ashr"
result1_strainero1.treatmenttm_shrink_ashr <- lfcShrink(dds_wald_local_1,
                                      type="ashr",
                                      res = result1_strainero1.treatmenttm)

############################
# -> ashr seems to be better
result1_strainero1.treatmenttm_shrink_ashr_df <- as.data.frame(result1_strainero1.treatmenttm_shrink_ashr)
result1_strainero1.treatmenttm_shrink_ashr_df <- result1_strainero1.treatmenttm_shrink_ashr_df[order(result1_strainero1.treatmenttm_shrink_ashr_df$padj),]

result1_strainero1.treatmenttm_shrink_ashr_df <- na.omit(result1_strainero1.treatmenttm_shrink_ashr_df) # 5890


write.csv(result1_strainero1.treatmenttm_shrink_ashr_df, file = "###")
DEG (padj<0.005): 972 genes
DEG1_strainero1.treatmenttm <- subset(result1_strainero1.treatmenttm_shrink_ashr_df,
                                 (result1_strainero1.treatmenttm_shrink_ashr_df$padj < 0.005))


DEG1_strainero1.treatmenttm <- tibble::rownames_to_column(DEG1_strainero1.treatmenttm, "Gene")
# -> 972 DEGs


DEG1_strainero1.treatmenttm <- merge(DEG1_strainero1.treatmenttm,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")


write.csv(DEG1_strainero1.treatmenttm, file = "###")
Identify DEGs for the strainero1.treatment35C interaction term.
Sample set 2: WT_25C / ero1_25C / WT_35C / ero1_35C
Subset
counts_raw_2 <- subset(counts_raw,
                       select = grepl("WT_25C|WT_35C|ero1_25C|ero1_35C",
                                     names(counts_raw)))

metadata_2 <- metadata[metadata$group %in% c("WT25C","WT35C","ero125C","ero135C"),]
Pre-filter and DESeq2
dds_2 <- DESeqDataSetFromMatrix(countData= round(counts_raw_2),
                              colData= metadata_2,
                              design= ~ strain + treatment + strain:treatment + rep)


# the read count cut-off of the low-expression genes
low_exp_read_count = 5
# minimum samples that express this gene (總共有 48 個 sample)
minimum_exp_sample = ncol(counts_raw_2)/2

keep <- rowSums(counts(dds_2) > low_exp_read_count) >= minimum_exp_sample
dds_2 <- dds_2[keep, ]

# 5886 genes
plotDispEsts: inspect the fit; this example uses fitType = local throughout
dds_wald_local_2 <- DESeq(dds_2,
              test = "Wald",
              fitType = "local",
              betaPrior = F)

summary(results(dds_wald_local_2))
out of 5886 with nonzero total read count
adjusted p-value < 0.1
LFC > 0 (up) : 1974, 34%
LFC < 0 (down) : 2039, 35%
outliers [1] : 11, 0.19%
low counts [2] : 0, 0%
(mean count < 5)Check ResultNames
dds_wald_local_2$strain
dds_wald_local_2$treatment
resultsNames(dds_wald_local_2)[1] WT WT WT ero1 ero1 ero1 WT WT WT ero1 ero1 ero1
Levels: WT ero1
[1] 25C 25C 25C 25C 25C 25C 35C 35C 35C 35C 35C 35C
Levels: 25C 35C
[1] "Intercept" "strain_ero1_vs_WT" "treatment_35C_vs_25C" "strainero1.treatment35C"**DEGs of **strainero1.treatment35C
Extract results of the interaction term strainero1.treatment35C
result2_strainero1.treatment35C <-results(dds_wald_local_2,
                                 name="strainero1.treatment35C",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result2_strainero1.treatment35C_df <- as.data.frame(result2_strainero1.treatment35C)
result2_strainero1.treatment35C_df <- result2_strainero1.treatment35C_df[order(result2_strainero1.treatment35C_df$padj),]


# check if any genes has baseMean = 0?
result2_strainero1.treatment35C_df[result2_strainero1.treatment35C_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result2_strainero1.treatment35C_df[is.na(result2_strainero1.treatment35C_df$pvalue) & is.na(result2_strainero1.treatment35C_df$padj),]
# -> 11 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result2_strainero1.treatment35C_df[is.na(result2_strainero1.treatment35C_df$padj) & !is.na(result2_strainero1.treatment35C_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result2_strainero1.treatment35C)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 4.564443
# as a result, 0% of genes were filtered out of the analysis


result2_strainero1.treatment35C_df <- na.omit(result2_strainero1.treatment35C_df) # 5875 gene

write.csv(result2_strainero1.treatment35C_df, file = "###")
lfcShrink (ashr)
# "ashr"
result2_strainero1.treatment35C_shrink_ashr <- lfcShrink(dds_wald_local_2,
                                      type="ashr",
                                      res = result2_strainero1.treatment35C)


############################
# -> ashr seems to be better
result2_strainero1.treatment35C_shrink_ashr_df <- as.data.frame(result2_strainero1.treatment35C_shrink_ashr)
result2_strainero1.treatment35C_shrink_ashr_df <- result2_strainero1.treatment35C_shrink_ashr_df[order(result2_strainero1.treatment35C_shrink_ashr_df$padj),]

result2_strainero1.treatment35C_shrink_ashr_df <- na.omit(result2_strainero1.treatment35C_shrink_ashr_df) # 5875 genes


write.csv(result2_strainero1.treatment35C_shrink_ashr_df, file = "###")
DEG (padj<0.005):** 3051 genes**
DEG2_strainero1.treatment35C <- subset(result2_strainero1.treatment35C_shrink_ashr_df,
                                 (result2_strainero1.treatment35C_shrink_ashr_df$padj < 0.005))


DEG2_strainero1.treatment35C <- tibble::rownames_to_column(DEG2_strainero1.treatment35C, "Gene")
# -> 3051 DEGs


DEG2_strainero1.treatment35C <- merge(DEG2_strainero1.treatment35C,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")


write.csv(DEG2_strainero1.treatment35C, file = "###")
Identify DEGs for straineK.treatmenttm, using ero1 as the reference.
Sample set 3: ero1_25C / eK_25C / ero1_tm / eK_tm
Subset
counts_raw_3 <- subset(counts_raw,
                       select = grepl("eK_25C|eK_tm|ero1_25C|ero1_tm",
                                     names(counts_raw)))

metadata_3 <- metadata[metadata$group %in% c("ero125C","eK25C","ero1tm","eKtm"),]
Pre-filter and DESeq2
dds_3 <- DESeqDataSetFromMatrix(countData= round(counts_raw_3),
                              colData= metadata_3,
                              design= ~ strain + treatment + strain:treatment + rep)


# the read count cut-off of the low-expression genes
low_exp_read_count = 5
# minimum samples that express this gene (總共有 48 個 sample)
minimum_exp_sample = ncol(counts_raw_3)/2
keep <- rowSums(counts(dds_3) > low_exp_read_count) >= minimum_exp_sample
dds_3 <- dds_3[keep, ]

# 5924 genes
plotDispEsts: inspect the fit; this example uses fitType = local throughout
dds_wald_local_3 <- DESeq(dds_3,
              test = "Wald",
              fitType = "local",
              betaPrior = F)

summary(results(dds_wald_local_3))
out of 5924 with nonzero total read count
adjusted p-value < 0.1
LFC > 0 (up) : 746, 13%
LFC < 0 (down) : 644, 11%
outliers [1] : 9, 0.15%
low counts [2] : 0, 0%
(mean count < 4)Check ResultNames
dds_wald_local_3$strain
dds_wald_local_3$treatment
resultsNames(dds_wald_local_3)[1] ero1 ero1 ero1 eK eK eK ero1 ero1 ero1 eK eK eK
Levels: ero1 eK
[1] 25C 25C 25C 25C 25C 25C tm tm tm tm tm tm
Levels: 25C tm
[1] "Intercept" "strain_eK_vs_ero1" "treatment_tm_vs_25C" "straineK.treatmenttm"**DEGs of **straineK.treatmenttm
Extract results of the interaction term straineK.treatmenttm
result3_straineK.treatmenttm <-results(dds_wald_local_3,
                                 name="straineK.treatmenttm",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result3_straineK.treatmenttm_df <- as.data.frame(result3_straineK.treatmenttm)
result3_straineK.treatmenttm_df <- result3_straineK.treatmenttm_df[order(result3_straineK.treatmenttm_df$padj),]


# check if any genes has baseMean = 0?
result3_straineK.treatmenttm_df[result3_straineK.treatmenttm_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result3_straineK.treatmenttm_df[is.na(result3_straineK.treatmenttm_df$pvalue) & is.na(result3_straineK.treatmenttm_df$padj),]
# -> 9 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result3_straineK.treatmenttm_df[is.na(result3_straineK.treatmenttm_df$padj) & !is.na(result3_straineK.treatmenttm_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result3_straineK.treatmenttm)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 4.248606
# as a result, 0% of genes were filtered out of the analysis


result3_straineK.treatmenttm_df <- na.omit(result3_straineK.treatmenttm_df) # 5915 gene

write.csv(result3_straineK.treatmenttm_df, file = "###")
lfcShrink (ashr)
# "ashr"
result3_straineK.treatmenttm_shrink_ashr <- lfcShrink(dds_wald_local_3,
                                      type="ashr",
                                      res = result3_straineK.treatmenttm)


############################
# -> ashr seems to be better
result3_straineK.treatmenttm_shrink_ashr_df <- as.data.frame(result3_straineK.treatmenttm_shrink_ashr)
result3_straineK.treatmenttm_shrink_ashr_df <- result3_straineK.treatmenttm_shrink_ashr_df[order(result3_straineK.treatmenttm_shrink_ashr_df$padj),]

result3_straineK.treatmenttm_shrink_ashr_df <- na.omit(result3_straineK.treatmenttm_shrink_ashr_df) # 5915 genes


write.csv(result3_straineK.treatmenttm_shrink_ashr_df, file = "###")
DEG (padj<0.005):** 636 genes**
DEG3_straineK.treatmenttm <- subset(result3_straineK.treatmenttm_shrink_ashr_df,
                                 (result3_straineK.treatmenttm_shrink_ashr_df$padj < 0.005))


DEG3_straineK.treatmenttm <- tibble::rownames_to_column(DEG3_straineK.treatmenttm, "Gene")
# -> 636 DEGs


DEG3_straineK.treatmenttm <- merge(DEG3_straineK.treatmenttm,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")


write.csv(DEG3_straineK.treatmenttm, file = "###")
Identify DEGs for straineK.treatment35C, using ero1 as the reference.
Sample set 4: ero1_25C / eK_25C / ero1_35C / eK_35C
Subset
counts_raw_4 <- subset(counts_raw,
                       select = grepl("eK_25C|eK_35C|ero1_25C|ero1_35C",
                                     names(counts_raw)))

metadata_4 <- metadata[metadata$group %in% c("ero125C","eK25C","ero135C","eK35C"),]
Pre-filter and DESeq2
dds_4 <- DESeqDataSetFromMatrix(countData= round(counts_raw_4),
                              colData= metadata_4,
                              design= ~ strain + treatment + strain:treatment + rep)


low_exp_read_count = 5
# minimum samples that express this gene (總共有 48 個 sample)
minimum_exp_sample = ncol(counts_raw_4)/2

# 至少在 >= 6 個 sample 中有 >5 的表達
keep <- rowSums(counts(dds_4) > low_exp_read_count) >= minimum_exp_sample
dds_4 <- dds_4[keep, ]

# 5945 genes
plotDispEsts: inspect the fit; this example uses fitType = local throughout
dds_wald_local_4 <- DESeq(dds_4,
              test = "Wald",
              fitType = "local",
              betaPrior = F)

summary(results(dds_wald_local_4))
out of 5945 with nonzero total read count
adjusted p-value < 0.1
LFC > 0 (up) : 689, 12%
LFC < 0 (down) : 557, 9.4%
outliers [1] : 9, 0.15%
low counts [2] : 0, 0%
(mean count < 5)Check ResultNames
dds_wald_local_4$strain
dds_wald_local_4$treatment
resultsNames(dds_wald_local_4)[1] ero1 ero1 ero1 eK eK eK ero1 ero1 ero1 eK eK eK
Levels: ero1 eK
[1] 25C 25C 25C 25C 25C 25C 35C 35C 35C 35C 35C 35C
Levels: 25C 35C
[1] "Intercept" "strain_eK_vs_ero1" "treatment_35C_vs_25C" "straineK.treatment35C"**DEGs of **straineK.treatment35C
Extract results of the interaction term straineK.treatment35C
result4_straineK.treatment35C <-results(dds_wald_local_4,
                                 name="straineK.treatment35C",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result4_straineK.treatment35C_df <- as.data.frame(result4_straineK.treatment35C)
result4_straineK.treatment35C_df <- result4_straineK.treatment35C_df[order(result4_straineK.treatment35C_df$padj),]


# check if any genes has baseMean = 0?
result4_straineK.treatment35C_df[result4_straineK.treatment35C_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result4_straineK.treatment35C_df[is.na(result4_straineK.treatment35C_df$pvalue) & is.na(result4_straineK.treatment35C_df$padj),]
# -> 9 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result4_straineK.treatment35C_df[is.na(result4_straineK.treatment35C_df$padj) & !is.na(result4_straineK.treatment35C_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result4_straineK.treatment35C)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 4.248606
# as a result, 0% of genes were filtered out of the analysis


result4_straineK.treatment35C_df <- na.omit(result4_straineK.treatment35C_df) # 5936 gene

write.csv(result4_straineK.treatment35C_df, file = "###")
lfcShrink
# "ashr"
result4_straineK.treatment35C_shrink_ashr <- lfcShrink(dds_wald_local_4,
                                      type="ashr",
                                      res = result4_straineK.treatment35C)

############################
# -> ashr seems to be better
result4_straineK.treatment35C_shrink_ashr_df <- as.data.frame(result4_straineK.treatment35C_shrink_ashr)
result4_straineK.treatment35C_shrink_ashr_df <- result4_straineK.treatment35C_shrink_ashr_df[order(result4_straineK.treatment35C_shrink_ashr_df$padj),]

result4_straineK.treatment35C_shrink_ashr_df <- na.omit(result4_straineK.treatment35C_shrink_ashr_df)


write.csv(result4_straineK.treatment35C_shrink_ashr_df, file = "###")
DEG (padj<0.005):** 636 genes**
DEG4_straineK.treatment35C <- subset(result4_straineK.treatment35C_shrink_ashr_df,
                                 (result4_straineK.treatment35C_shrink_ashr_df$padj < 0.005))


DEG4_straineK.treatment35C <- tibble::rownames_to_column(DEG4_straineK.treatment35C, "Gene")
# -> 517 DEGs


DEG4_straineK.treatment35C <- merge(DEG4_straineK.treatment35C,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")


write.csv(DEG4_straineK.treatment35C, file = "###")
Using all sample (not split) to discover DEGs in interaction terms
WT_25C / ero1_25C / WT_tm / ero1_tm / WT_35C / ero1_35C / eK_25C / eK_tm / eK_35C
Subset all necessary samples
counts_raw_5 <- subset(counts_raw,
                       select = grepl("WT_25C|WT_tm|WT_35C|ero1_25C|ero1_tm|ero1_35C|eK_25C|eK_tm|eK_35C",
                                     names(counts_raw)))

metadata_5 <- metadata[metadata$group %in% c("WT25C","WTtm","ero125C","ero1tm","WT35C","ero135C","eK25C","eKtm","eK35C"),]
Pre-filter and DESeq2
dds_5 <- DESeqDataSetFromMatrix(countData= round(counts_raw_5),
                              colData= metadata_5,
                              design= ~ strain + treatment + strain:treatment + rep)


# the read count cut-off of the low-expression genes
low_exp_read_count = 5
# minimum samples that express this gene
minimum_exp_sample = ncol(counts_raw_5)/2

# 至少在 >= 6 個 sample 中有 >5 的表達
keep <- rowSums(counts(dds_5) > low_exp_read_count) >= minimum_exp_sample
dds_5 <- dds_5[keep, ]

# 5927 genes
plotDispEsts: inspect the fit; this example uses fitType = local throughout
dds_wald_local_5 <- DESeq(dds_5,
              test = "Wald",
              fitType = "local",
              betaPrior = F)


summary(results(dds_wald_local_5))
out of 5927 with nonzero total read count
adjusted p-value < 0.1
LFC > 0 (up) : 1953, 33%
LFC < 0 (down) : 1910, 32%
outliers [1] : 8, 0.13%
low counts [2] : 0, 0%
(mean count < 5)Check ResultNames
dds_wald_local_5$strain
dds_wald_local_5$treatment
resultsNames(dds_wald_local_5)[1] WT WT WT ero1 ero1 ero1 eK eK eK WT WT WT ero1 ero1 ero1 eK eK eK WT WT WT ero1 ero1 ero1 eK eK eK
Levels: WT ero1 eK
[1] 25C 25C 25C 25C 25C 25C 25C 25C 25C tm tm tm tm tm tm tm tm tm 35C 35C 35C 35C 35C 35C 35C 35C 35C
Levels: 25C tm 35C
[1] "Intercept" "strain_ero1_vs_WT" "strain_eK_vs_WT" "treatment_tm_vs_25C" "treatment_35C_vs_25C"
[6] "strainero1.ewq" "straineK.treatmenttm" "strainero1.treatment35C" "straineK.treatment35C"Intersection
strainero1.treatmenttm
In order to compare with section 1, reference strain has to be WT
dds_wald_local_5$strain <- relevel(dds_wald_local_5$strain, ref="WT")

dds_wald_local_5 <- nbinomWaldTest(dds_wald_local_5)

# check
resultsNames(dds_wald_local_5)
Extract results of the interaction term strainero1.treatmenttm
result5_strainero1.treatmenttm <-results(dds_wald_local_5,
                                 name="strainero1.treatmenttm",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result5_strainero1.treatmenttm_df <- as.data.frame(result5_strainero1.treatmenttm)
result5_strainero1.treatmenttm_df <- result5_strainero1.treatmenttm_df[order(result5_strainero1.treatmenttm_df$padj),]


# check if any genes has baseMean = 0?
result5_strainero1.treatmenttm_df[result5_strainero1.treatmenttm_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result5_strainero1.treatmenttm_df[is.na(result5_strainero1.treatmenttm_df$pvalue) & is.na(result5_strainero1.treatmenttm_df$padj),]
# -> 8 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result5_strainero1.treatmenttm_df[is.na(result5_strainero1.treatmenttm_df$padj) & !is.na(result5_strainero1.treatmenttm_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result5_strainero1.treatmenttm)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 5.358176
# as a result, 0% of genes were filtered out of the analysis


result5_strainero1.treatmenttm_df <- na.omit(result5_strainero1.treatmenttm_df) # -> 5919 gene

write.csv(result5_strainero1.treatmenttm_df, file = "###")
lfcShrink
# "ashr"
result5_strainero1.treatmenttm_shrink_ashr <- lfcShrink(dds_wald_local_5,
                                      type="ashr",
                                      res = result5_strainero1.treatmenttm)

############################
# -> ashr seems to be better
result5_strainero1.treatmenttm_shrink_ashr_df <- as.data.frame(result5_strainero1.treatmenttm_shrink_ashr)
result5_strainero1.treatmenttm_shrink_ashr_df <- result5_strainero1.treatmenttm_shrink_ashr_df[order(result5_strainero1.treatmenttm_shrink_ashr_df$padj),]

result5_strainero1.treatmenttm_shrink_ashr_df <- na.omit(result5_strainero1.treatmenttm_shrink_ashr_df)


write.csv(result5_strainero1.treatmenttm_shrink_ashr_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_strainero1.treatmenttm_lfcShrink.csv")
DEG (padj<0.005):** 1053 genes**
DEG5_strainero1.treatmenttm <- subset(result5_strainero1.treatmenttm_shrink_ashr_df,
                                 (result5_strainero1.treatmenttm_shrink_ashr_df$padj < 0.005))


DEG5_strainero1.treatmenttm <- tibble::rownames_to_column(DEG5_strainero1.treatmenttm, "Gene")
# -> 1053 DEGs


DEG5_strainero1.treatmenttm <- merge(DEG5_strainero1.treatmenttm,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")

write.csv(DEG5_strainero1.treatmenttm, file = "###")
ggvenn: compare with section 3 DEG
ggvenn(list('section 1' = DEG1_strainero1.treatmenttm$Gene,
            'section 5 (all samples)' = DEG5_strainero1.treatmenttm$Gene),
       c("section 1",
         "section 5 (all samples)"))
Export these intersected 904 genes
DEG5_DEG1_strainero1.treatmenttm <-
DEG5_strainero1.treatmenttm[DEG5_strainero1.treatmenttm$Gene %in% intersect(DEG1_strainero1.treatmenttm$Gene,DEG5_strainero1.treatmenttm$Gene),]

write.csv(DEG5_DEG1_strainero1.treatmenttm, file = "###")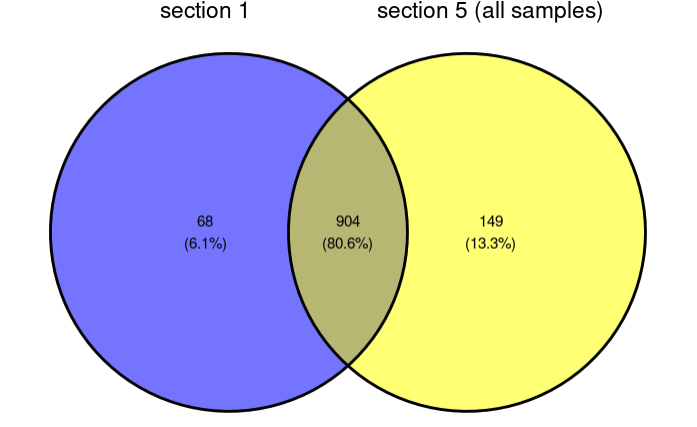
strainero1.treatment35C
In order to compare with section 2, reference strain has to be WT
dds_wald_local_5$strain <- relevel(dds_wald_local_5$strain, ref="WT")

dds_wald_local_5 <- nbinomWaldTest(dds_wald_local_5)

# check
resultsNames(dds_wald_local_5)
Extract results of the interaction term strainero1.treatment35C
result5_strainero1.treatment35C <-results(dds_wald_local_5,
                                 name="strainero1.treatment35C",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result5_strainero1.treatment35C_df <- as.data.frame(result5_strainero1.treatment35C)
result5_strainero1.treatment35C_df <- result5_strainero1.treatment35C_df[order(result5_strainero1.treatment35C_df$padj),]


# check if any genes has baseMean = 0?
result5_strainero1.treatment35C_df[result5_strainero1.treatment35C_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result5_strainero1.treatment35C_df[is.na(result5_strainero1.treatment35C_df$pvalue) & is.na(result5_strainero1.treatment35C_df$padj),]
# -> 8 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result5_strainero1.treatment35C_df[is.na(result5_strainero1.treatment35C_df$padj) & !is.na(result5_strainero1.treatment35C_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result5_strainero1.treatment35C)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 5.358176
# as a result, 0% of genes were filtered out of the analysis


result5_strainero1.treatment35C_df <- na.omit(result5_strainero1.treatment35C_df) # -> 5919 gene

write.csv(result5_strainero1.treatment35C_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_strainero1.treatment35C_no.lfcShrink.csv")
lfcShrink
# "ashr"
result5_strainero1.treatment35C_shrink_ashr <- lfcShrink(dds_wald_local_5,
                                      type="ashr",
                                      res = result5_strainero1.treatment35C)

############################
# -> ashr seems to be better
result5_strainero1.treatment35C_shrink_ashr_df <- as.data.frame(result5_strainero1.treatment35C_shrink_ashr)
result5_strainero1.treatment35C_shrink_ashr_df <- result5_strainero1.treatment35C_shrink_ashr_df[order(result5_strainero1.treatment35C_shrink_ashr_df$padj),]

result5_strainero1.treatment35C_shrink_ashr_df <- na.omit(result5_strainero1.treatment35C_shrink_ashr_df)


write.csv(result5_strainero1.treatment35C_shrink_ashr_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_strainero1.treatment35C_lfcShrink.csv")
DEG (padj<0.005):** 3302 genes**
DEG5_strainero1.treatment35C <- subset(result5_strainero1.treatment35C_shrink_ashr_df,
                                 (result5_strainero1.treatment35C_shrink_ashr_df$padj < 0.005))


DEG5_strainero1.treatment35C <- tibble::rownames_to_column(DEG5_strainero1.treatment35C, "Gene")
# -> 3302 genes


DEG5_strainero1.treatment35C <- merge(DEG5_strainero1.treatment35C,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")

write.csv(DEG5_strainero1.treatment35C, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DEGs_strainero1.treatment35C.csv")
ggvenn: compare with section 3 DEG
ggvenn(list('section 2' = DEG2_strainero1.treatment35C$Gene,
            'section 5 (all samples)' = DEG5_strainero1.treatment35C$Gene),
       c("section 2",
         "section 5 (all samples)"))
Export these intersected 3021 genes
DEG5_DEG2_strainero1.treatment35C <-
DEG5_strainero1.treatment35C[DEG5_strainero1.treatment35C$Gene %in% intersect(DEG2_strainero1.treatment35C$Gene,DEG5_strainero1.treatment35C$Gene),]

write.csv(DEG5_DEG2_strainero1.treatment35C, file = "DEG_Interaction/08_intersect-02_05/DEGs_strainero1.treatment35C.csv")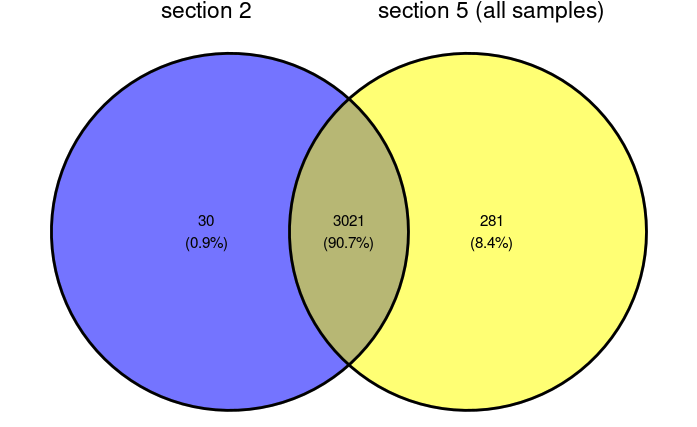
straineK.treatmenttm
In order to compare with section 3, reference strain has to be ero1
dds_wald_local_5$strain <- relevel(dds_wald_local_5$strain, ref="ero1")

dds_wald_local_5 <- nbinomWaldTest(dds_wald_local_5)

# check
resultsNames(dds_wald_local_5)
Extract results of the interaction term straineK.treatmenttm
result5_straineK.treatmenttm <-results(dds_wald_local_5,
                                 name="straineK.treatmenttm",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result5_straineK.treatmenttm_df <- as.data.frame(result5_straineK.treatmenttm)
result5_straineK.treatmenttm_df <- result5_straineK.treatmenttm_df[order(result5_straineK.treatmenttm_df$padj),]


# check if any genes has baseMean = 0?
result5_straineK.treatmenttm_df[result5_straineK.treatmenttm_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result5_straineK.treatmenttm_df[is.na(result5_straineK.treatmenttm_df$pvalue) & is.na(result5_straineK.treatmenttm_df$padj),]
# -> 8 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result5_straineK.treatmenttm_df[is.na(result5_straineK.treatmenttm_df$padj) & !is.na(result5_straineK.treatmenttm_df$pvalue),]
# -> 有 0 個 genes 被 independent filtered

metadata(result5_straineK.treatmenttm)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 5.358176
# as a result, 0% of genes were filtered out of the analysis


result5_straineK.treatmenttm_df <- na.omit(result5_straineK.treatmenttm_df) # -> 5919 gene

write.csv(result5_straineK.treatmenttm_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_straineK.treatmenttm_no.lfcShrink.csv")
lfcShrink
# "ashr"
result5_straineK.treatmenttm_shrink_ashr <- lfcShrink(dds_wald_local_5,
                                      type="ashr",
                                      res = result5_straineK.treatmenttm)

############################
# -> ashr seems to be better
result5_straineK.treatmenttm_shrink_ashr_df <- as.data.frame(result5_straineK.treatmenttm_shrink_ashr)
result5_straineK.treatmenttm_shrink_ashr_df <- result5_straineK.treatmenttm_shrink_ashr_df[order(result5_straineK.treatmenttm_shrink_ashr_df$padj),]

result5_straineK.treatmenttm_shrink_ashr_df <- na.omit(result5_straineK.treatmenttm_shrink_ashr_df)


write.csv(result5_straineK.treatmenttm_shrink_ashr_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_straineK.treatmenttm_lfcShrink.csv")
DEG (padj<0.005):** 621 genes**
DEG5_straineK.treatmenttm <- subset(result5_straineK.treatmenttm_shrink_ashr_df,
                                 (result5_straineK.treatmenttm_shrink_ashr_df$padj < 0.005))


DEG5_straineK.treatmenttm <- tibble::rownames_to_column(DEG5_straineK.treatmenttm, "Gene")
# -> 621 DEGs


DEG5_straineK.treatmenttm <- merge(DEG5_straineK.treatmenttm,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")

write.csv(DEG5_straineK.treatmenttm, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DEGs_straineK.treatmenttm.csv")
ggvenn: compare with section 3 DEG
ggvenn(list('section 3' = DEG3_straineK.treatmenttm$Gene,
            'section 5 (all samples)' = DEG5_straineK.treatmenttm$Gene),
       c("section 3",
         "section 5 (all samples)"))
Export these intersected 544 genes
DEG5_DEG3_straineK.treatmenttm <-
DEG5_straineK.treatmenttm[DEG5_straineK.treatmenttm$Gene %in% intersect(DEG3_straineK.treatmenttm$Gene,DEG5_straineK.treatmenttm$Gene),]

write.csv(DEG5_DEG3_straineK.treatmenttm, file = "DEG_Interaction/07_intersect-03_05/DEGs_straineK.treatmenttm.csv")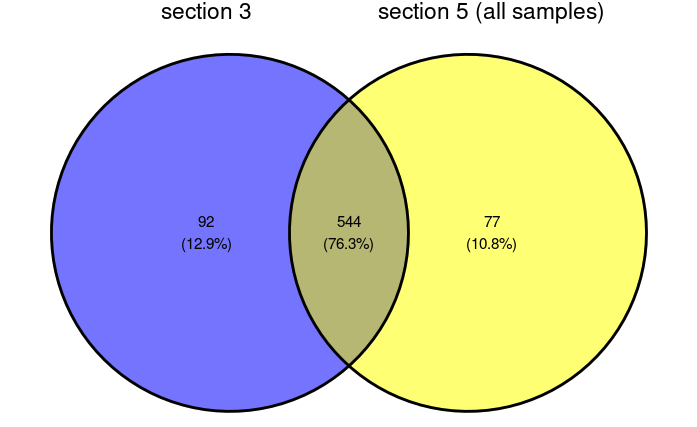
straineK.treatment35C
In order to compare with section 4, reference strain has to be ero1
dds_wald_local_5$strain <- relevel(dds_wald_local_5$strain, ref="ero1")

dds_wald_local_5 <- nbinomWaldTest(dds_wald_local_5)

# check
resultsNames(dds_wald_local_5)
Extract results of the interaction term straineK.treatment35C
result5_straineK.treatment35C <-results(dds_wald_local_5,
                                 name="straineK.treatment35C",
                                 alpha = 0.05,
                                 lfcThreshold = 0, # default
                                 independentFiltering = TRUE,
                                 pAdjustMethod = "fdr")


result5_straineK.treatment35C_df <- as.data.frame(result5_straineK.treatment35C)
result5_straineK.treatment35C_df <- result5_straineK.treatment35C_df[order(result5_straineK.treatment35C_df$padj),]


# check if any genes has baseMean = 0?
result5_straineK.treatment35C_df[result5_straineK.treatment35C_df$baseMean == 0,]
# 0 genes

# check if there are any outlier: pvalue and padj = NA?
result5_straineK.treatment35C_df[is.na(result5_straineK.treatment35C_df$pvalue) & is.na(result5_straineK.treatment35C_df$padj),]
# -> 8 genes 是 outlier

# check how many genes were filtered by automatic independent filtering, for having a low mean normalized count: only padj = NA?
result5_straineK.treatment35C_df[is.na(result5_straineK.treatment35C_df$padj) & !is.na(result5_straineK.treatment35C_df$pvalue),]
# -> 有 230 個 genes 被 independent filtered

metadata(result5_straineK.treatment35C)$filterThreshold
# DESeq2 has filtered out genes with a mean count of 41.12458
# as a result, 3.877551% of genes were filtered out of the analysis


result5_straineK.treatment35C_df <- na.omit(result5_straineK.treatment35C_df) # -> 5689 gene

write.csv(result5_straineK.treatment35C_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_straineK.treatment35C_no.lfcShrink.csv")
lfcShrink
# "ashr"
result5_straineK.treatment35C_shrink_ashr <- lfcShrink(dds_wald_local_5,
                                      type="ashr",
                                      res = result5_straineK.treatment35C)

############################
# -> ashr seems to be better
result5_straineK.treatment35C_shrink_ashr_df <- as.data.frame(result5_straineK.treatment35C_shrink_ashr)
result5_straineK.treatment35C_shrink_ashr_df <- result5_straineK.treatment35C_shrink_ashr_df[order(result5_straineK.treatment35C_shrink_ashr_df$padj),]

result5_straineK.treatment35C_shrink_ashr_df <- na.omit(result5_straineK.treatment35C_shrink_ashr_df)


write.csv(result5_straineK.treatment35C_shrink_ashr_df, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DESeq2_res_straineK.treatment35C_lfcShrink.csv")
DEG (padj<0.005):** 434 genes**
DEG5_straineK.treatment35C <- subset(result5_straineK.treatment35C_shrink_ashr_df,
                                 (result5_straineK.treatment35C_shrink_ashr_df$padj < 0.005))


DEG5_straineK.treatment35C <- tibble::rownames_to_column(DEG5_straineK.treatment35C, "Gene")
# -> 434 DEGs


DEG5_straineK.treatment35C <- merge(DEG5_straineK.treatment35C,
                             geneID_transform %>% dplyr::select(Gene, gene_name),
                             by = "Gene")

write.csv(DEG5_straineK.treatment35C, file = "DEG_Interaction/05_WT&ero1&eK.vs.tm&35C&25C/DEGs_straineK.treatment35C.csv")
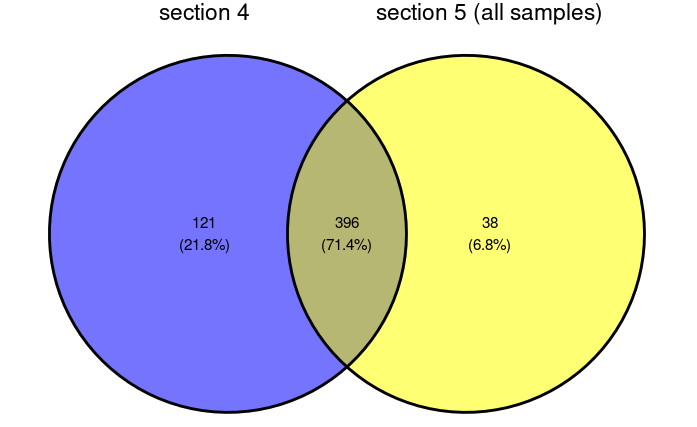
ggvenn: compare with section 4 DEG
ggvenn(list('section 4' = DEG4_straineK.treatment35C$Gene,
            'section 5 (all samples)' = DEG5_straineK.treatment35C$Gene),
       c("section 4",
         "section 5 (all samples)"))
Export these intersected 396 genes
DEG5_DEG4_straineK.treatment35C <-
DEG5_straineK.treatment35C[DEG5_straineK.treatment35C$Gene %in% intersect(DEG4_straineK.treatment35C$Gene,DEG5_straineK.treatment35C$Gene),]

write.csv(DEG5_DEG4_straineK.treatment35C, file = "DEG_Interaction/06_intersect-04_05/DEGs_straineK.treatment35C.csv")